
PS5LM
llama.cpp on a jailbroken PlayStation 5. Run any GGUF language model on the console itself, first on its Zen 2 CPU, then on its GPU.
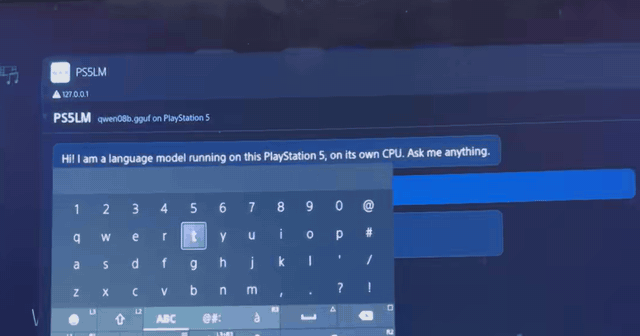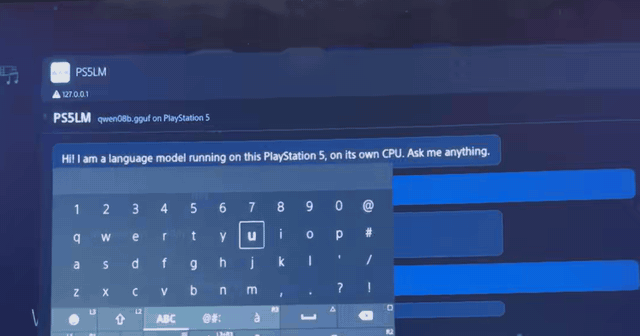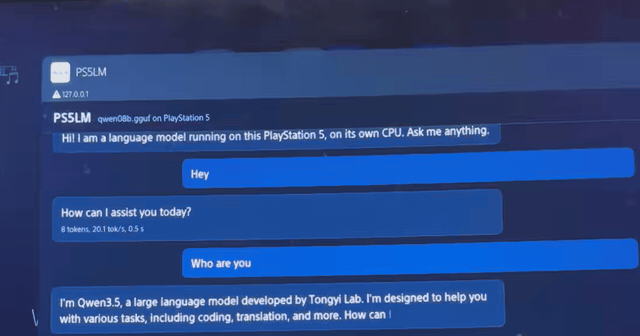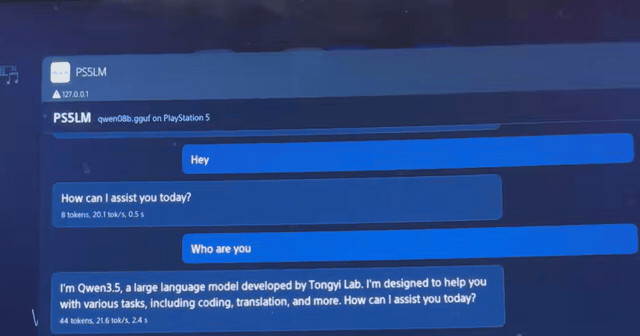
ps5lm.cobanov.dev: the full demo video and how it works
The first target is Qwen 3.8 (27B, hybrid Gated DeltaNet attention), the newest open Qwen. No one has run it on a PS5 yet.
Status: v0.1 is out. One payload,
ps5lm.elf, opens a model library in the PS5's browser: download a model on the console, run it, chat. Small models for now (up to 1.6 GB, Qwen3.5 0.8B and 2B). See docs/ROADMAP.md and docs/CONSOLE.md.New: Qwen 3.8 27B on the GPU. A native app (
ps5/app) runs llama.cpp's Vulkan backend on Mihawk-99's RADV port with the console's 12 GiB of direct memory: Qwen3.8-27B UD-IQ2_XXS answers at 9 to 21 tok/s, chat athttp://<console IP>:8081. Built from source for now (below).
Install
You need a PS5 you own on firmware 7.00 to 13.60, jailbroken, with a payload loader (Payload Manager from WebKit Autoloader, or elfldr on port 9021).
From Payload Manager, which also brings updates:
- Settings: turn on Multiple Payload Sources.
- Add the source
https://ps5lm.cobanov.dev/payloads.json. - Install PS5LM from the list and load it.
Or by hand: download ps5lm.elf from the latest release and load it like any payload (upload it in Payload Manager, or send it to an ELF loader on port 9021).
Once it runs, the PS5's browser opens the PS5LM library. Press Download on a model, then Run, then Open chat. Type with the DualSense.
The library also works from a phone or computer on the same network at http://<console IP>:8082, and the chat at port 8081 speaks the OpenAI API. Models are stored in /data/PS5LM/models; a GGUF copied there over FTP shows up too.
Limits for now: a payload can only keep about 1.6 GB of model locked in memory without starving the home screen, so the catalog has Qwen3.5 0.8B (13 to 21 tok/s) and Qwen3.5 2B (about 9 tok/s). Bigger models need a native app (#4).
Why llama.cpp
Earlier PS5 LLM work hand-writes GPU kernels for one model at a time. PS5LM ports llama.cpp itself, so every architecture and every quantization llama.cpp supports comes along: Qwen, Llama, Mistral, Gemma, from 1-bit to 8-bit. Qwen 3.8's smallest open model is 27B, and only the 2 to 3 bit quants fit in the console's memory, which llama.cpp already has.
Layout
| Path | What |
|---|---|
third_party/llama.cpp |
upstream llama.cpp, pinned as a submodule |
ps5/compat |
the few libc functions the console lacks |
ps5/app |
the native app: llama-server on the GPU through RADV, its icon and param.json |
patches/ |
PS5 changes to llama.cpp's source, kept small |
probes/ |
memprobe and threadprobe: what a payload gets on the console |
scripts/ |
SDK setup, the llama.cpp cross build, sending payloads |
docs/ |
roadmap, models that fit, porting notes, research |
Building from source
Needs the ps5-payload-dev SDK and a host LLVM.
# macOS
brew install llvm@21 lld socat cmake ninja
# Debian / Ubuntu
sudo apt install clang-18 lld-18 socat cmake ninja-build

git clone --recursive https://github.com/cobanov/PS5LM
cd PS5LM
scripts/setup-sdk.sh
source scripts/env.sh

make -C probes/memprobe          # Phase 0 probe
scripts/build-llama.sh           # llama-cli, llama-server, llama-bench for the PS5
Running on the console
You need a PS5 you own on firmware 7.00 to 13.60, jailbroken, with an ELF loader listening on port 9021 (elfldr).
scripts/host-relapse.sh          # serves the Relapse exploit page; open it in the PS5's browser
export PS5_HOST=192.168.1.50     # your console
scripts/console-setup.sh         # FTP, kernel log and shell payloads
scripts/send.sh probes/memprobe/memprobe.elf
The probe streams its results back and also writes them to /data/PS5LM/memprobe.txt on the console.
With ftpsrv running too (port 2121), scripts/run.sh uploads a llama.cpp tool and starts it with arguments:
# copy a model to /data/PS5LM/models first (FTP or USB)
scripts/run.sh llama-cli -m /data/PS5LM/models/model.gguf -p "Hello from a PS5" -n 64
scripts/run.sh llama-server -m /data/PS5LM/models/model.gguf --host 0.0.0.0 --port 8081
The GPU app
The app links llama.cpp with ggml-vulkan against PS5_Vulkan's RADV build. Set up PS5_Vulkan and its forks in .deps/src (PS5_Vulkan, PS5_Mesa and PS5_PayloadSDK at the revisions PS5_Vulkan pins), then:
(cd .deps/src/PS5_Vulkan && tools/setup-native-dependencies.sh && tools/build-radv.sh release && make app)
scripts/build-app.sh             # build/app-ps5/title/PPSA99581
Copy build/app-ps5/title/PPSA99581 to /data/homebrew/PPSA99581 and a model to /data/PS5LM/models, then start PS5LM from the home screen. The chat is at http://<console IP>:8081 once the model is on the GPU (about 90 s).
On the TV the app shows a dashboard drawn with ps5-homebrew-ui (a submodule in third_party/): generation speed, how busy the GPU is, CPU use, the memory pool the GPU and CPU share and how the model, its KV cache and the rest split it, context in use, and the model. Cross on the Model tile opens the model library: every .gguf in /data/PS5LM/models and on USB drives (/mnt/usbN or /mnt/usbN/PS5LM/models), each with the context and KV cache type the planner (ps5/app/model_plan.cpp) picks for the memory free, and the sampling settings of its family when it is a model we know (Qwen 3.5/3.6/3.8, Gemma 4, gpt-oss, Granite, Nemotron, Mistral, Llama). It lists internal storage and USB drives in separate sections; Cross loads a model from either. llama.cpp reads the whole file into GPU memory (no mmap), so a model on USB loads at the drive's speed and the drive is not touched afterwards.
/data/PS5LM/app-args.txt (one argument per line) overrides the planner. The app logs to /data/PS5LM/app.log and llama.log.
From the PC:
scripts/preview-app-ui.sh                  # render the dashboard to build/app-preview/*.png (Mesa, no console)
PS5_HOST=<console IP> scripts/ps5lm-app.sh cycle   # close, deploy, launch; also close|deploy|launch
The app closes itself on request (/data/PS5LM/quit), so nothing is killed while it draws; launching uses ps5-homebrew-dev-protocol's launch payload, cloned into .deps/src.
Credits
- llama.cpp / ggml, which does the actual work.
- PS5_Vulkan (Mihawk-99) for RADV on the PS5, and ps5-homebrew-ui, ps5-opengl and ps5-homebrew-dev-protocol (BlackBearReloaded) for the app's screen and tooling.
- ps5-payload-dev (John Törnblom) for the SDK and the ELF loader.
- PS5SX2, ProsperoAI and PS5_Vulkan, whose notes on the console's memory and GPU this project leans on.
Licence
GPL-3.0-or-later, see LICENSE. llama.cpp keeps its MIT licence. No Sony SDK files, keys, firmware or model weights are in this repository.
PS5LM is not affiliated with Sony Interactive Entertainment or Alibaba. "PlayStation" and "PS5" are trademarks of Sony Interactive Entertainment.