
Install · Benchmarks · Models · Docs
Install
Requirements: a Mac with Apple silicon (M1 or newer) and macOS 14 Sonoma or later.
brew install nace-ai/tap/kapitsa
# or: curl -fsSL https://raw.githubusercontent.com/nace-ai/kapitsa/main/install.sh | bash
kapitsa opencode --model 35b # also: kapitsa claude, kapitsa codex, kapitsa piOn a 16-24 GB Mac use --model 4b. kapitsa serve starts the chat page and the
OpenAI and Anthropic APIs at http://127.0.0.1:8000. Kapitsa updates itself. Usage guide
Benchmarks
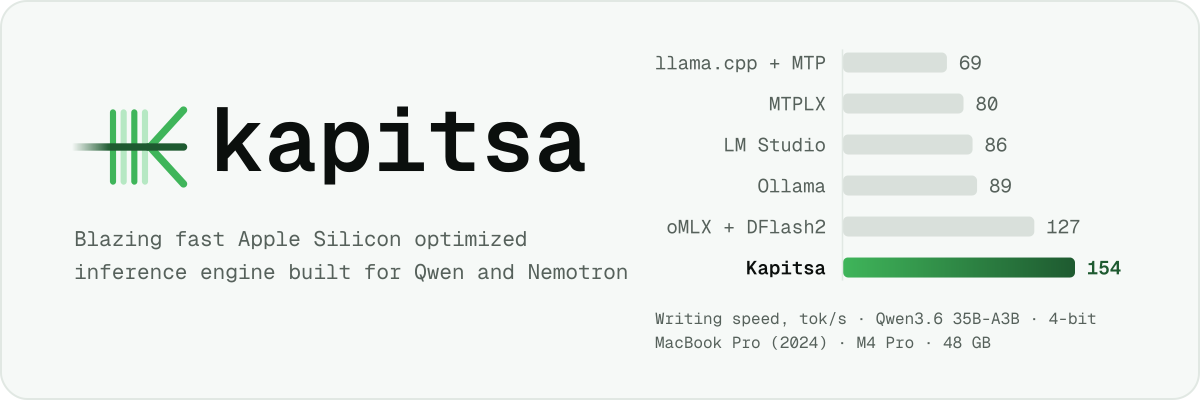
Writing speed of a coding answer, each engine in its fastest setup. 🟩 fastest per model · — not measured · details
MacBook Pro (16-inch, 2024) · M4 Pro · 48 GB
Qwen
| Model | Kapitsa | oMLX | mlx‑serve | Ollama | MTPLX | LM Studio | llama.cpp | MLX | Rapid‑MLX |
|---|---|---|---|---|---|---|---|---|---|
| Qwen3.5 4B 4-bit |
🟩 179 tok/s | 102 | 137 | 109 | 104 | 81 | 70 | 88 | 98 |
| Qwen3.8 27B 4-bit |
🟩 63 tok/s | 45 | 54 | 32 | 36 | 15 | 18 | 28 | — |
| Qwen3.6 35B‑A3B 4-bit |
🟩 154 tok/s | 127 | 124 | 89 | 80 | 86 | 69 | 86 | — |
Nemotron
| Model | Kapitsa | oMLX | llama.cpp | MLX |
|---|---|---|---|---|
| Nemotron Dory1.0 4B NVFP4 |
🟩 64 tok/s | — no support |
6 | 48 |
| Nemotron 3.5 Lightning 30B‑A3B NVFP4 |
🟩 106 tok/s | — | — | 65 |
| Nemotron 3.5 Bolt 74B‑A9B 2/4/8-bit mix |
🟩 64 tok/s | 35 | — no Metal support |
32 |
MacBook Pro (16-inch, 2026) · M5 Max · 128 GB
Qwen
| Model | Kapitsa | oMLX | mlx‑serve | Ollama | MTPLX | LM Studio | llama.cpp | MLX | Rapid‑MLX |
|---|---|---|---|---|---|---|---|---|---|
| Qwen3.5 4B 4-bit |
🟩 294 tok/s | — | — | 213 | 175 | 154 | — | 135 | — |
| Qwen3.8 27B 4-bit |
🟩 115 tok/s | — | — | 68 | 69 | 32 | — | 30 | — |
| Qwen3.6 35B‑A3B 4-bit |
🟩 272 tok/s | 232 | — | 166 | 123 | 127 | — | 112 | — |
| Qwen3.8 Flash‑Next 180B‑A7B 4-bit |
105 tok/s | 107 | 🟩 108 | 60 | 88 | — won't load |
96 | 77 | — |
Nemotron
| Model | Kapitsa | oMLX | mlx‑serve | Ollama | MTPLX | LM Studio | llama.cpp | MLX |
|---|---|---|---|---|---|---|---|---|
| Nemotron Dory1.0 4B NVFP4 |
— | — | — no support |
— no support |
— no support |
— no support |
— | — |
| Nemotron 3.5 Lightning 30B‑A3B NVFP4 |
🟩 239 tok/s | 190 | 190 | 153 | 131 | 110 | 159 | 139 |
| Nemotron 3.5 Bolt 74B‑A9B 2/4/8-bit mix |
🟩 127 tok/s | — | — no support |
— no support |
— no support |
— no support |
— no Metal support |
— |
| Nemotron 3.5 Super‑VL 120B‑A12B NVFP4 |
🟩 85 tok/s | 52 | — | 64 | — | 61 | 66 | 46 |
MacBook Pro (14-inch, 2021) · M1 Pro · 16 GB
Qwen
| Model | Kapitsa | oMLX | mlx‑serve | Ollama | MTPLX | LM Studio | llama.cpp | MLX | Rapid‑MLX |
|---|---|---|---|---|---|---|---|---|---|
| Qwen3.5 4B 4-bit |
🟩 85 tok/s | 55 | 62 | 55 | 42 | 47 | 38 | 46 | — |
Nemotron
| Model | Kapitsa | oMLX | llama.cpp | MLX |
|---|---|---|---|---|
| Nemotron Dory1.0 4B NVFP4 |
🟩 40 tok/s | — no support |
4 | 30 |
Measure your Mac: kapitsa bench --submit adds it to the community results.
Models
| Model | Download | Speculation |
|---|---|---|
Qwen3.5-4B · 4bdense |
4-bit · 4.6 GB also 6-bit 5.6 · 8-bit 6.7 · bf16 10.6 GB |
DFlash / MTP |
Qwen3.8-27B · 27bdense |
4-bit · 20.2 GB also 5-bit 23.5 · 6-bit 26.9 · 8-bit 33.6 · bf16 58.8 GB |
DFlash2 / MTP |
Qwen3.6-35B-A3B · 35bMoE, 3B active |
4-bit · 22.1 GB also 5-bit 26.4 · 6-bit 30.7 · 8-bit 39.4 · bf16 71.9 GB |
DFlash2 / MTP |
Qwen3.8-Flash-Next 180B-A7B · flash-nextMoE, 7B active; 128 GB Macs |
4-bit · 105.9 GB 4/6/8-bit MLX; its 32 GB n-gram table stays on the SSD |
MTP |
Nemotron Dory1.0 4B · dorylooped dense, 1-4 loops per token; text only |
NVIDIA NVFP4 · 3.2 GB also bf16 8.0 GB |
— |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid Mamba-2 MoE, 3B active; text only |
NVIDIA NVFP4 · 22.9 GB 4-bit NVFP4 experts, FP8, BF16 |
DSpark |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid Mamba-2 MoE, 9B active |
NVIDIA 24 GB · 25.1 GB 2-bit experts, NVFP4, 8-bit |
LiLiCorr |
Nemotron 3.5 Super-VL 120B-A12B · superhybrid Mamba-2 MoE, 12B active; 96 GB+ Macs |
NVIDIA NVFP4 · 76.4 GB 4-bit NVFP4 experts, FP8, BF16 |
LiLiCorr |
Other precisions: --model 35b:6bit. All but Lightning and Dory read images. Memory: 16 GB for the 4B models, 32 GB
for the 27B, 35B, Lightning and Bolt, 96 GB for Super-VL, 128 GB for Flash-Next. Details
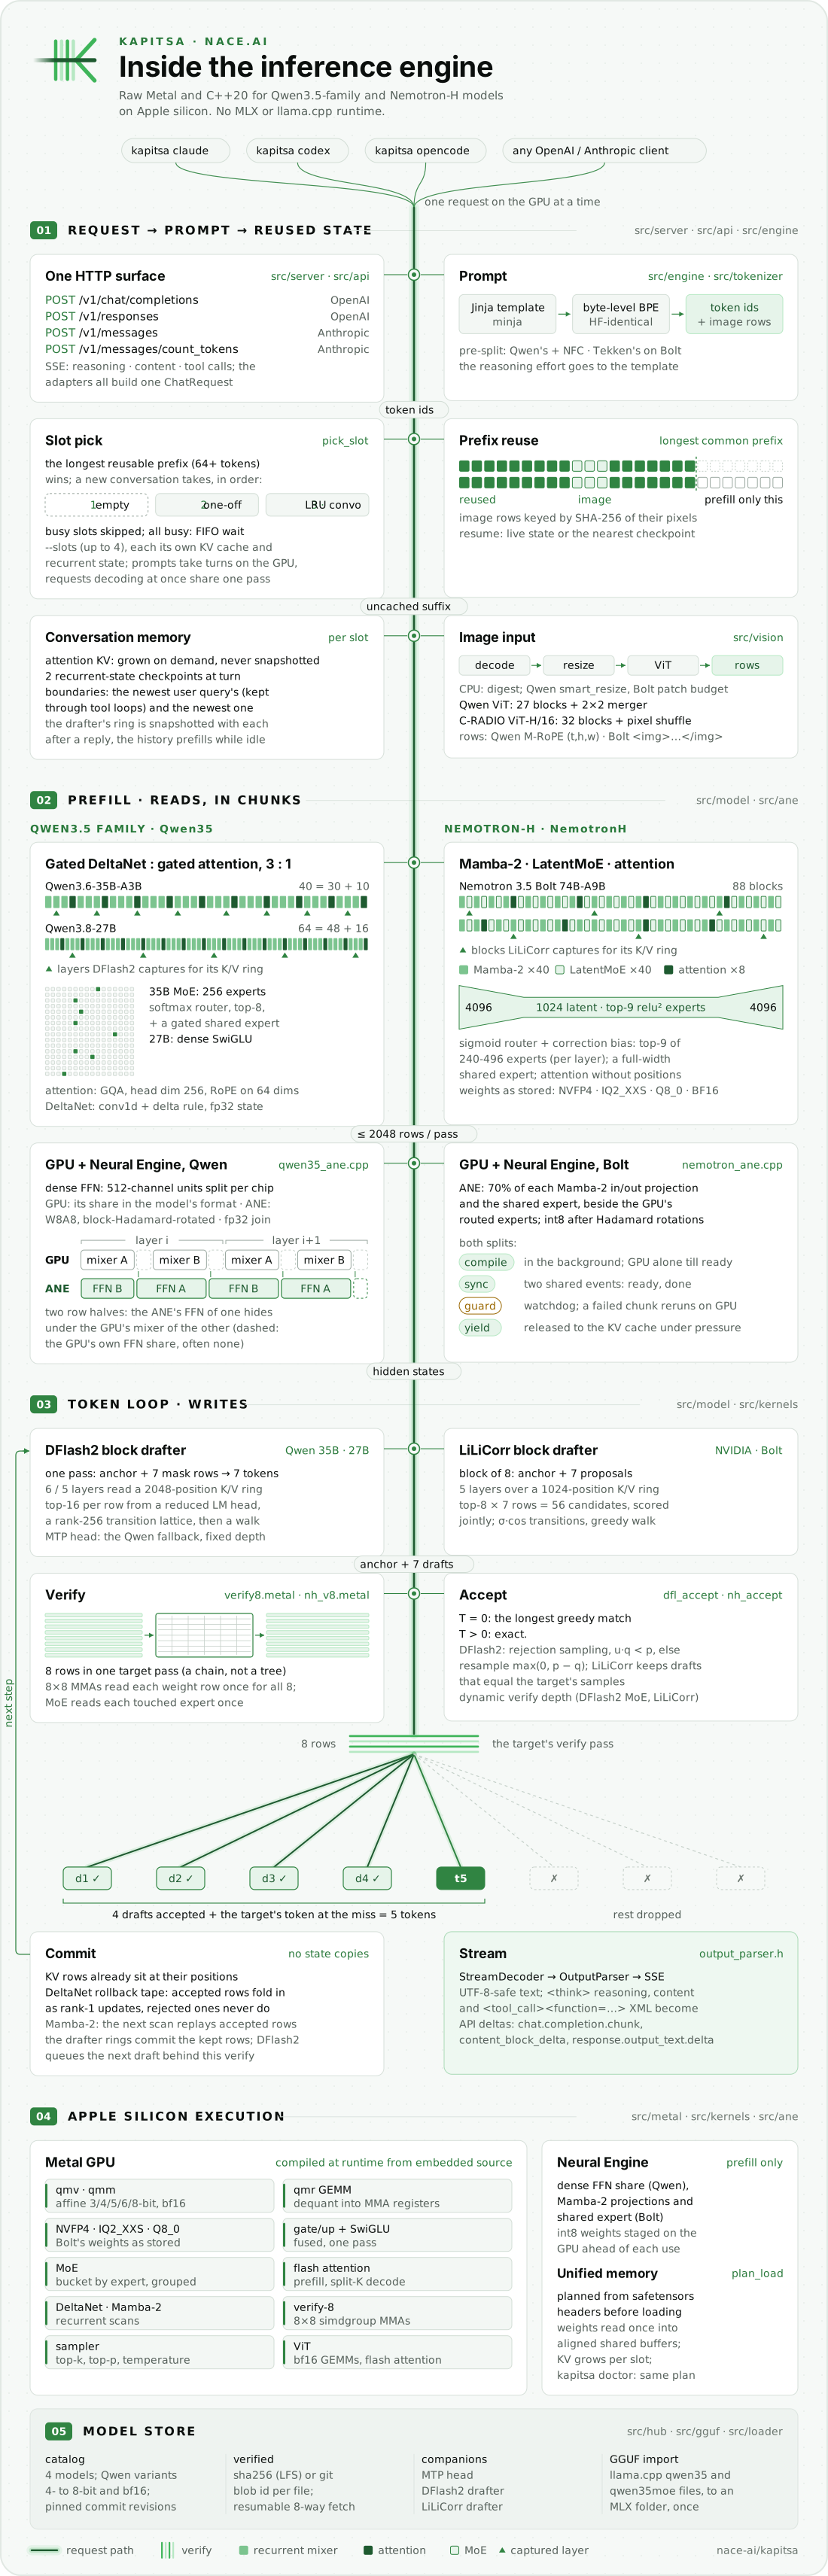
How it works
Architecture · Contributing · Press kit · Apache 2.0, © 2026 Nace AI · Third-party notices