
PolyStrata
English · 简体中文 · 日本語 · Deutsch · Français · Español · Português
Run large AI models on your own PC
Qwen3.8-Flash-Next, GLM 5.3 Flash, DeepSeek V4 Flash, LFM2.5, Qwen3.6, Ornith 1.5, Gemma 4, Tiel Coder and MiniCPM-V · free and open source

Claude Code on Qwen3.6-35B-A3B UD-Q3_K_M, on the laptop with the 8 GB card, in real time: it adds a --json option to a small program, writes a test for it and runs the tests. The server had read Claude Code's system prompt when it started ("warm_start": true).
A voxel pagoda garden, 1 shot prompt running on an RTX 5070 with Strata (Qwen3.8-Flash-Next IQ3_S, 128K context) ·
full video (49 s)
PolyStrata runs large AI models on a normal PC, models that usually need a server. They chat, write code and work with your apps and coding agents. Nothing leaves your PC.
It runs nine models, on two engines:
- Qwen3.8-Flash-Next on an NVIDIA or AMD graphics card with 12 GB or more, on Windows or Linux. It also reads pictures. Its engine is the Strata project's, unchanged.
The other eight run on an engine written for PolyStrata, with one NVIDIA card or two: on Linux, and the six smaller ones on Windows too. They are experimental: they have run on one PC with a 32 GB card, and the six smaller ones on a laptop with an 8 GB card as well.
- GLM 5.3 Flash, the largest: a file of 79 to 114 GB, most of which stays in RAM.
- DeepSeek V4 Flash, a file of 91 GB, most of which stays in RAM too. Its memory of a conversation is small: a 128K context takes 0.7 GB more VRAM than 32K.
- LFM2.5-24B-A2B by Liquid AI, a file of 11 to 25 GB. Most of its layers have no attention, so a long conversation takes little VRAM: a 128K context takes 2 GB more than 32K. Its license allows commercial use only to companies with less than 10 million dollars of yearly revenue.
- Qwen3.6-35B-A3B, a file of 13 to 23 GB. It also reads pictures.
- Ornith 1.5, which has Qwen3.6-35B-A3B's architecture and other weights: a file of 14 to 24 GB. It also reads pictures.
- Gemma 4 26B-A4B, a file of 11 to 17 GB. It also reads pictures.
- Tiel Coder 35B-A3B, Ornith 1.5 quantized for coding agents by peculiar-ragdoll: a file of 14 to 23 GB. It also reads pictures.
- MiniCPM-V 4.7 35B-A3B by OpenBMB, which has Qwen3.6-35B-A3B's architecture and weights of its own, made to read pictures: a file of 16 to 29 GB.
The server can change between installed models while it runs (how).
PolyStrata is built on Strata by Niko1221. Why it is a separate repo, AMD and smaller cards, fine-tunes and other questions: FAQ.
How fast is it?
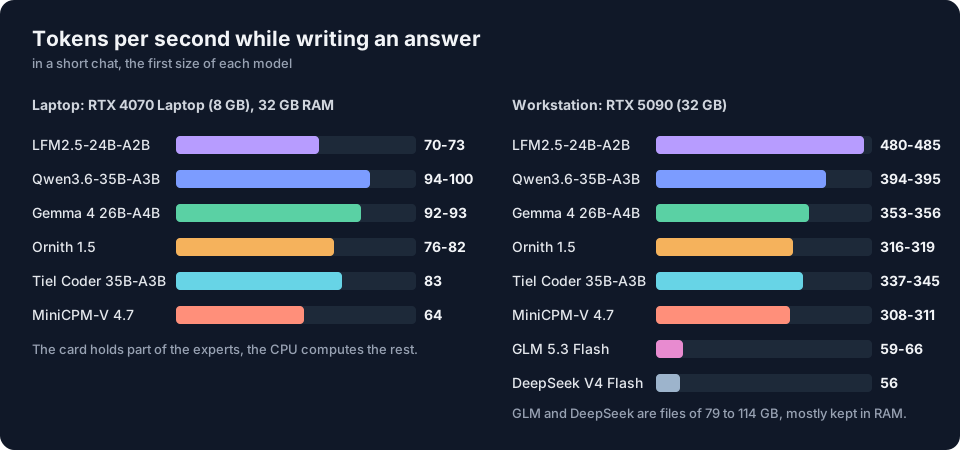
A token is about ¾ of a word.
- Writes answers: how fast the reply appears in a short chat. 60 tokens per second is faster than you can read.
- Reads your prompt: how fast it takes in what you send (a document, code or a chat history).
Qwen3.8-Flash-Next
Measured by the Strata project on two ordinary gaming PCs, with a 32K-token prompt.
| NVIDIA: RTX 5070 (12 GB), Ryzen 5 7600, 64 GB RAM | AMD: RX 9070 XT (16 GB), Ryzen 9 3900X, 47 GB RAM | ||||||||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
NVIDIA: Q2_0 with engine 0.1.36, the other rows with 0.1.26 (4K answers, 32K prompts). The full tables are in DETAILS.md. A card with more VRAM is faster: an RTX 3090 (24 GB) should write about 100-140 tokens per second. Long chats and other cards: speed of each size, community results.
GLM 5.3 Flash
Measured for PolyStrata on one workstation, with a short chat and a 29K-token prompt.
| NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
GLM 5.3 Flash is a much larger model than the others, and about a fifth of its experts fit in this card's 32 GB, so it writes more slowly. What was measured and how: docs/GLM.md.
DeepSeek V4 Flash
Measured for PolyStrata on the same workstation, with a short chat and a 30K-token prompt.
| NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||
|---|---|---|---|---|---|---|
|
On the same PC llama.cpp wrote 25 to 28 tokens per second and read a prompt of 3,384 tokens at 96. A prompt of 116,473 tokens in a 128K context was read and answered in 174 seconds, one of 487,529 tokens in a 512K context in 32 minutes, and both times the three facts hidden in it were found. What was measured and how: docs/DEEPSEEK.md.
LFM2.5-24B-A2B
Measured the same way as Qwen3.6-35B-A3B below, on the same two PCs, with a prompt of about 30,000 tokens.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
On the laptop Q8_0 fills the 32 GB of RAM, which is what makes it slow there; the workstation holds every size whole.
With --n-cpu-moe 25, the best of the settings tried on the laptop, llama.cpp b11540 read a prompt of 32,000 tokens
there at 530 tokens/s and wrote after it at 53; PolyStrata read it at 3,540 and wrote at 71 to 73. On the workstation
llama-bench read 29,816 tokens at 13,300 tokens/s with llama.cpp's default batch of 512 and at 23,600 with 2,048, as
fast as PolyStrata, and wrote one token at a time at 455 tokens/s and at 369 after that prompt, where PolyStrata
writes at 452 and 387. A prompt of about 124,000 tokens in a 128K context was read and answered in 8.7 seconds on the
workstation; the laptop read it in 45 seconds.
Qwen3.6-35B-A3B
Measured for PolyStrata on two PCs, with a short chat and a prompt of 30,000 to 32,000 tokens: on the left a laptop whose card has 8 GB, where the processor runs the experts the card has no room for, and on the right a workstation whose card holds the whole model.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
A prompt of 10,000 tokens is read at 1,660 tokens/s on the laptop and at 6,300 on the workstation. The workstation's card held to 8 GB, a stand-in from before the laptop was measured, is in docs/BACKENDS.md.
Ornith 1.5
Measured the same way, on the same two PCs.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
A prompt of 10,000 tokens is read at 1,590 tokens/s on the laptop and at 6,400 on the workstation.
Gemma 4 26B-A4B
Measured the same way, on the same two PCs.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
A prompt of 10,000 tokens is read at 2,130 tokens/s on the laptop and at 6,800 on the workstation.
Tiel Coder 35B-A3B
Measured the same way, on the same two PCs.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
A prompt of 10,000 tokens is read at 1,670 tokens/s on the laptop and at 6,300 on the workstation.
MiniCPM-V 4.7 35B-A3B
Measured the same way, on the same two PCs. Its file has no draft block, so it writes one token at a time.
| NVIDIA: RTX 4070 Laptop (8 GB), Core i7-14700HX, 32 GB RAM | NVIDIA: RTX 5090 (32 GB), Xeon Platinum 8470Q (25 vCPU), 120 GB RAM | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
A prompt of 10,000 tokens is read at 1,260 tokens/s on the laptop and at 8,790 on the workstation. On the laptop Q6_K fills the 32 GB of RAM, which is what makes it slow there.
The eight models of PolyStrata's own engine were measured with its benchmark, which you can run on your PC:
python polystrata.py benchmark --model <name> --prompt-tokens 24000
(what it sends and prints).
What others measured on their own cards, and how to compare with llama.cpp on yours:
community results.
On the laptop PolyStrata read prompts 2.7 to 3.5 times as fast as llama.cpp b11540 and wrote 1.5 to 1.8 times
as fast, with Qwen3.6 and with Tiel Coder (the two runs).
What you need
Qwen3.8-Flash-Next
| Graphics card | NVIDIA GeForce RTX 20, 30, 40 or 50 series, or AMD Radeon RX 7900 XT / XTX, RX 7800 XT / 7700 XT, RX 9060 XT, RX 9070 / 9070 XT, Radeon AI PRO R9700 or RX 6800 / 6900 series. It needs 12 GB of VRAM or more. |
| RAM | 32 GB or more. Your RAM decides which size fits. 64 GB runs every size. |
| Disk | About 80 GB free. Use an SSD if you can: the first start is much faster. |
| System | Windows 10 / 11 or Linux, and a current graphics driver from NVIDIA or AMD. |
The installer sets up everything else. Two or three cards can share the model (multi-GPU).
Experimental, written and tested by community members on their own machines:
- Older graphics cards (Tesla P40 / V100, GTX 10, Radeon VII / MI50, RX 6700 XT, RX 5500 XT): Older GPUs.
- Intel Arc, built from source on Linux: Intel Arc.
- Apple Silicon Macs (M1 to M5), built from source by
./setup.sh(the Metal engine): Mac. - AMD Ryzen AI Max (Strix Halo), built from source on Linux: Strix Halo.
- Older processors without AVX2: they work, but slowly. Older CPUs.
The full list: docs/INSTALL.md.
GLM 5.3 Flash
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer. It has run on 32 GB of VRAM only. About 12 GB are taken before any expert, so a 12 GB card cannot start it. |
| RAM | Beside a 32 GB card, 96 GB or more for the whole model, 82 GB for its 2-bit size, 60 GB for the size with half the experts. A smaller card needs more RAM (how much). It has run with 120 GB. |
| Disk | 114 GB, 102 GB or 79 GB for the model file, on an SSD. |
| System | Linux, and a current NVIDIA driver. |
The installer sets up everything else. It compiles the engine on your PC and offers to install what that needs (g++ and the CUDA toolkit). Not yet: AMD cards, two cards on Windows, three cards or more, pictures. A user runs it on Windows with one 24 GB card and 128 GB of RAM (report).
The full list: docs/GLM.md.
DeepSeek V4 Flash
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer. It has run on 32 GB of VRAM only. About 11.5 GB are taken before any expert, so a 12 GB card cannot start it. |
| RAM | Beside a 32 GB card, 72 GB or more, the installer's estimate. A smaller card needs more RAM (how much). It has run with 120 GB. |
| Disk | 91 GB for the model's three files, on an SSD. |
| System | Linux, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. Not tried yet: AMD cards, two cards. It reads text only. A user runs it on Windows with one 24 GB card and 128 GB of RAM (report).
The full list: docs/DEEPSEEK.md.
LFM2.5-24B-A2B
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 4 GB are taken before any expert. It has run on a laptop's 8 GB card and on a 32 GB card. |
| RAM | About 16, 18, 20, 27 or 31 GB beside an 8 GB card for UD-Q3_K_XL, QAD-Q4_0, UD-Q4_K_XL, UD-Q6_K_XL and Q8_0, the installer's estimate. A card with 24 GB holds the three smaller sizes whole. All five have run on a laptop with 32 GB. |
| Disk | 11 to 25 GB for the model file. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as for Qwen3.6-35B-A3B below. It has not been tried on an AMD card. It reads text only. Liquid AI's license allows commercial use only to companies with less than 10 million dollars of yearly revenue (LFM Open License v1.0).
The full list: docs/LFM.md.
Qwen3.6-35B-A3B
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 5 GB are taken before any expert. It has run on a 32 GB card, on that card held to 8 GB, and on a laptop's 8 GB card. On Linux an AMD card can run it as a beta: setup compiles the engine on your PC; tested so far with Qwen3.6 and Ornith on an RX 7600. |
| RAM | About 17, 21 or 27 GB beside an 8 GB card for the three sizes, the installer's estimate. A card with 24 GB holds the two smaller sizes whole. All three sizes have run on a laptop with 32 GB. |
| Disk | 13, 17 or 23 GB for the model file, 1 GB more to read pictures. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. On Windows it downloads the engine ready-made from the latest release. On a processor without AVX2, or in a copy whose engine changed after that release, it compiles the engine instead with Visual Studio's 2022 compiler and the CUDA toolkit, and offers to install them. Not yet: AMD cards on Windows, two cards on Windows, three cards or more.
Since its 0.1.44 the Strata project's own engine runs Qwen3.6 too, from UD-Q4_K_XL up
(--family qwen36-strata, 32 GB of RAM or more). On an RTX 5090 with UD-Q4_K_XL it read a 4K prompt 1.6 times as fast
as strata-poly; a 31K prompt and writing came out about even (measured). The smaller sizes, for
8 GB cards, stay on strata-poly.
Ornith 1.5
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 4 GB are taken before any expert. It has run on a 32 GB card, on that card held to 8 GB, and on a laptop's 8 GB card. On Linux an AMD card can run it as a beta: setup compiles the engine on your PC; tested so far with Qwen3.6 and Ornith on an RX 7600. |
| RAM | About 18, 22 or 28 GB beside an 8 GB card for the three sizes, the installer's estimate. A card with 24 GB holds the two smaller sizes whole. All three sizes have run on a laptop with 32 GB. |
| Disk | 14, 17 or 24 GB for the model file, 1 GB more to read pictures. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. On Windows it downloads the engine ready-made from the latest release. On a processor without AVX2, or in a copy whose engine changed after that release, it compiles the engine instead with Visual Studio's 2022 compiler and the CUDA toolkit, and offers to install them. Not yet: AMD cards on Windows, two cards on Windows, three cards or more.
Gemma 4 26B-A4B
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 6 GB are taken before any expert. It has run on a 32 GB card, on that card held to 8 GB, and on a laptop's 8 GB card. On Linux an AMD card can run it as a beta: setup compiles the engine on your PC; tested so far with Qwen3.6 and Ornith on an RX 7600. |
| RAM | About 15, 18 or 21 GB beside an 8 GB card for the three sizes, the installer's estimate. By the same estimate a card with 16 GB holds the two smaller sizes whole. All three sizes have run on a laptop with 32 GB. |
| Disk | 11, 13 or 17 GB for the model file and its draft model, 1 GB more to read pictures. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. On Windows it downloads the engine ready-made from the latest release. On a processor without AVX2, or in a copy whose engine changed after that release, it compiles the engine instead with Visual Studio's 2022 compiler and the CUDA toolkit, and offers to install them. Not yet: AMD cards on Windows, two cards on Windows, three cards or more.
Tiel Coder 35B-A3B
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 5 GB are taken before any expert. It has run on a 32 GB card, on that card held to 8 GB, and on a laptop's 8 GB card. On Linux an AMD card can run it as a beta: setup compiles the engine on your PC; tested so far with Qwen3.6 and Ornith on an RX 7600. |
| RAM | About 18, 21 or 27 GB beside an 8 GB card for the three sizes, the installer's estimate. A card with 24 GB holds all three sizes whole. All three sizes have run on a laptop with 32 GB. |
| Disk | 14, 17 or 23 GB for the model file, 1 GB more to read pictures. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. On Windows it downloads the engine ready-made from the latest release. On a processor without AVX2, or in a copy whose engine changed after that release, it compiles the engine instead with Visual Studio's 2022 compiler and the CUDA toolkit, and offers to install them. Not yet: AMD cards on Windows, two cards on Windows, three cards or more.
MiniCPM-V 4.7 35B-A3B
| Graphics card | One NVIDIA GeForce RTX 20 series card or newer with 8 GB of VRAM or more. About 3.5 GB are taken before any expert. It has run on a 32 GB card and on a laptop's 8 GB card. On Linux an AMD card can run it as a beta: setup compiles the engine on your PC; it has run on an RX 7600. |
| RAM | About 19, 25 or 31 GB beside an 8 GB card for the three sizes, the installer's estimate. A card with 32 GB holds all three sizes whole. All three sizes have run on a laptop with 32 GB. |
| Disk | 16, 21 or 29 GB for the model file, 1 GB more to read pictures. |
| System | Linux or Windows 10 / 11, and a current NVIDIA driver. |
The installer sets up everything else, as it does for GLM 5.3 Flash. On Windows it downloads the engine ready-made from the latest release. On a processor without AVX2, or in a copy whose engine changed after that release, it compiles the engine instead with Visual Studio's 2022 compiler and the CUDA toolkit, and offers to install them. Not yet: AMD cards on Windows, two cards on Windows, three cards or more.
What each of the five needs and how it was checked: docs/BACKENDS.md.
Install
Let your AI set it up
Do you use an AI coding assistant (Claude Code, Cursor, Codex, GitHub Copilot, ...)? Paste this into it:
Set up PolyStrata on this PC for me: https://github.com/VecSzn/PolyStrata - follow docs/AI_SETUP.md in that repository.
It checks your graphics card, RAM and disk and picks the model that fits. Then it installs and starts it and tells you how to connect your apps. AI tools can also install, start and stop PolyStrata through its MCP server.
Or do it yourself
Download PolyStrata and unzip it (or git clone it).
Windows: double-click START-HERE.bat. Linux: run ./setup.sh in the PolyStrata folder.
Mac (Apple Silicon, M1 to M5, macOS 15 or newer): install Apple's Command Line Tools once
(xcode-select --install in Terminal; Xcode itself is not needed). Then open Terminal in the PolyStrata folder and run
./setup.sh. It builds the Mac engine on your Mac (about 7 minutes), asks the same questions, downloads the model
and starts it. Next time, ./setup.sh starts it right away. Which size fits your Mac and how fast it is:
docs/MAC.md.
The installer finds your card and sets up the right engine for it. It asks you a few questions:
- which model and which size,
- how much context (how much text the model keeps in mind),
- whether it should read pictures (GLM 5.3 Flash, DeepSeek V4 Flash and LFM2.5 read none).
Press Enter each time for the recommended answer. Then it downloads the model (about 70 GB for Qwen3.8-Flash-Next,
79 to 114 GB for GLM 5.3 Flash, 91 GB for DeepSeek V4 Flash, 11 to 29 GB for the other six) and starts it. If the download stops, run it again:
it continues where it left off. Your browser opens the PolyStrata app at http://127.0.0.1:8080.
All nine are in the installer's list of models. ./setup.sh --family glm, deepseek, lfm25, qwen36, ornith,
gemma4, tiel or minicpmv goes straight to one (what it asks and writes).
While the model starts, your PC can be slow or stop responding for 1-3 minutes (longest the first time). PolyStrata loads 35-55 GB into your RAM and locks part of it for the graphics card. This is normal. Wait, and don't close the window. The window shows what PolyStrata is doing.
Next time, run START-HERE.bat (or ./setup.sh) again. It starts right away and downloads nothing twice. Close
its window to stop the model. UPDATE.bat (./update.sh) updates PolyStrata without starting it. Updating, Docker,
several cards, where the files go and every option: docs/INSTALL.md.
Is it fast on your PC? Run BENCH.bat (./bench.sh): about 5-10 minutes, it measures chat, 4K/16K prompts and an agent-style session with your own settings and writes a report to share (how).
Which model should I pick?
Qwen3.8-Flash-Next
The installer recommends one for your RAM. The same model comes in several sizes, compressed more or less. Smaller sizes are faster. Larger sizes are a bit smarter.
| Your RAM | Take | Why |
|---|---|---|
| 32 GB | Coder | it fits 32 GB, and it is made for code (with a 24 GB card, Q2_0 and IQ2_XS run too) |
| 48 GB | IQ2_XS (or Q2_0, the fastest) | the larger sizes do not fit |
| 64 GB | IQ2_XS (recommended), or IQ3_XXS / IQ3_S | every size fits; IQ3_S is the best and the slowest |
| 96 GB or more | IQ3_S, or Unsloth's UD-IQ4_XS (~4-bit) | room for the largest sizes with everything else open |
- Coder: a coding version with half of the experts removed. It reaches 91% of the full model's SWE-bench Verified score (measured by its authors) and fits 32 GB of RAM. It is weaker outside code, including Chinese and other CJK text (#438). For those, take Q2_0, IQ2_XS or IQ3_S, which keep every expert.
- Swift 1.5: a fine-tune that thinks for a much shorter time before it answers. You get the answer sooner, at about the same quality.
- Unsloth UD-IQ4_XS: Unsloth's ~4-bit version, between IQ3_S and UD-Q4_K_XL in quality. A 94 GB download. With less than ~80 GB of RAM, PolyStrata reads part of it from the SSD while it answers, so it is slower there (an NVMe SSD helps).
- Unsloth UD-Q4_K_XL, UD-Q5_K_XL, UD-Q6_K_XL and Q8_0: 4- to 8-bit, closer to the full model (93-95% the same next token as Q8_0). Fast where every expert fits in RAM (~88 GB for UD-Q4_K_XL up to ~136 GB for Q8_0); with less RAM PolyStrata reads part of them from the SSD while it answers, which is much slower (7-8.5 tokens/s for UD-Q4_K_XL on a 64 GB PC).
- OrcaRouter's Uncensored IQ3_XXS: you set it up by hand. It is not in the installer's menu.
Sizes, downloads and what fits where: docs/MODELS.md. To add another model later, run
SETUP.bat (Linux: ./setup.sh --setup).
GLM 5.3 Flash
Three sizes so far. The installer takes the first one your RAM is enough for.
| Size | What it is | Download | RAM beside a 32 GB card |
|---|---|---|---|
| 3.0BIT | the whole model, at about 3 bits (neuralll) | 114 GB | 96 GB |
| UD-IQ2_XXS | the whole model, at about 2 bits (Unsloth): it reads a prompt faster and writes more slowly | 102 GB | 82 GB |
| REAP50-Q3_K_M | half of the routed experts removed (REAP50 by patrickbdevaney) | 79 GB | 60 GB |
Your graphics card decides how much RAM it needs, because the experts the card does not hold have to stay in RAM.
| Your graphics card | 3.0BIT | UD-IQ2_XXS | REAP50-Q3_K_M | |
|---|---|---|---|---|
| 32 GB | 96 GB | 82 GB | 60 GB | the PC it has run on (120 GB of RAM) |
| 24 GB | about 104 GB | about 90 GB | about 68 GB | not run yet |
| 16 GB | about 113 GB | about 99 GB | about 77 GB | not run yet |
| 12 GB or less | it does not start |
The RAM numbers are the installer's estimate from the one PC it has run on. With less RAM it still starts, but it reads experts from the SSD while it answers and gets much slower. The installer says so and asks first.
Other quantizations of GLM 5.3 Flash are not supported yet: what is missing.
DeepSeek V4 Flash
One size so far.
| Size | What it is | Download | RAM beside a 32 GB card |
|---|---|---|---|
| UD-IQ2_XXS | the whole model at about 2 bits (Unsloth) | 91 GB | 72 GB |
As with GLM 5.3 Flash, the experts the card does not hold stay in RAM: about 80 GB beside a 24 GB card and 89 GB beside a 16 GB card, by the installer's estimate, and a 12 GB card cannot start it. Only the 32 GB card has been tried.
LFM2.5-24B-A2B
Five sizes. The installer takes UD-Q4_K_XL, or UD-Q3_K_XL when the PC has too little RAM for it. The others are
chosen by name: --model QAD-Q4_0.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| UD-Q4_K_XL | the whole model with 4-bit experts (Unsloth) | 15 GB | about 20 GB |
| UD-Q3_K_XL | the same with 3-bit experts: the least RAM | 11 GB | about 16 GB |
| QAD-Q4_0 | 4-bit, from Liquid AI, trained to lose less to that quantization | 14 GB | about 18 GB |
| UD-Q6_K_XL | 6-bit experts | 22 GB | about 27 GB |
| Q8_0 | 8-bit throughout, the closest to the model as trained | 25 GB | about 31 GB |
Against Q8_0, on five prompts of 256 tokens each, the other sizes pick Q8_0's most likely token at 96.8% of the steps (UD-Q6_K_XL), 95.5% (UD-Q4_K_XL), 92.7% (QAD-Q4_0) and 91.6% (UD-Q3_K_XL).
Qwen3.6-35B-A3B
Three sizes so far. The installer takes UD-Q3_K_M, or UD-Q2_K_XL when the PC has too little RAM for it. UD-Q4_K_M is chosen by name: --model UD-Q4_K_M.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| UD-Q3_K_M | the whole model with 3-bit experts (Unsloth) | 17 GB | about 21 GB |
| UD-Q2_K_XL | the same with 2- and 3-bit experts: the least RAM | 13 GB | about 17 GB |
| UD-Q4_K_M | the same with 4-bit experts | 23 GB | about 27 GB |
A larger card holds more of the model and needs less RAM: with UD-Q3_K_M about 17 GB beside a 12 GB card, 13 GB beside a 16 GB card, and 10 GB once the card holds all of it. These are the installer's estimates. They have not been checked on such a PC.
Ornith 1.5
Three sizes so far. The installer takes APEX-I-COMPACT, or APEX-I-MINI when the PC has too little RAM for it. APEX-I-QUALITY is chosen by name: --model APEX-I-QUALITY.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| APEX-I-COMPACT | the whole model with 3- and 4-bit experts (APEX by mudler) | 17 GB | about 22 GB |
| APEX-I-MINI | the same with 2- and 3-bit experts: the least RAM | 14 GB | about 18 GB |
| APEX-I-QUALITY | the same with 4- to 6-bit experts | 24 GB | about 28 GB |
A larger card holds more of the model and needs less RAM: with APEX-I-COMPACT about 17 GB beside a 12 GB card, 13 GB beside a 16 GB card, and 10 GB once the card holds all of it. These are the installer's estimates. They have not been checked on such a PC.
Gemma 4 26B-A4B
Three sizes so far. The installer takes UD-Q3_K_M, or UD-Q2_K_XL when the PC has too little RAM for it. UD-Q4_K_M is chosen by name: --model UD-Q4_K_M.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| UD-Q3_K_M | the whole model with 3-bit experts (Unsloth), and Google's draft model for it | 13 GB | about 18 GB |
| UD-Q2_K_XL | the same with 2-bit experts: the least RAM | 11 GB | about 15 GB |
| UD-Q4_K_M | the same with 4- and 5-bit experts | 17 GB | about 21 GB |
A larger card holds more of the model and needs less RAM: with UD-Q3_K_M about 14 GB beside a 12 GB card, and 10 GB once the card holds all of it. These are the installer's estimates. They have not been checked on such a PC.
Tiel Coder 35B-A3B
Three sizes so far. The installer takes UD-Q3_K_XL, or UD-IQ3_XXS when the PC has too little RAM for it. UD-Q4_K_XL is chosen by name: --model UD-Q4_K_XL.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| UD-Q3_K_XL | the whole model with 3- and 4-bit experts (peculiar-ragdoll) | 17 GB | about 21 GB |
| UD-IQ3_XXS | the same with 2- and 3-bit experts: the least RAM | 14 GB | about 18 GB |
| UD-Q4_K_XL | the same with 4- to 6-bit experts | 23 GB | about 27 GB |
A larger card holds more of the model and needs less RAM: with UD-Q3_K_XL about 17 GB beside a 12 GB card, 13 GB beside a 16 GB card, and 10 GB once the card holds all of it. These are the installer's estimates. They have not been checked on such a PC.
MiniCPM-V 4.7 35B-A3B
Three sizes so far, from OpenBMB. The installer takes Q4_K_M, or mix_q3gud_im when the PC has too little RAM for it.
Q6_K is chosen by name: --model Q6_K.
| Size | What it is | Download | RAM beside an 8 GB card |
|---|---|---|---|
| Q4_K_M | the whole model with 4-bit experts (OpenBMB) | 21 GB | about 25 GB |
| mix_q3gud_im | the same with 3- and 4-bit experts: the least RAM | 16 GB | about 19 GB |
| Q6_K | the same with 6-bit experts | 29 GB | about 31 GB |
Using it
All nine models are used the same way: the same app, the same API.

The app's Monitor (left) while a coding agent writes the pagoda garden from the video (right). A screenshot from Strata.
- In the browser: open
http://127.0.0.1:8080. It has Chat, a live Monitor of the model and your GPU/CPU/RAM, and About with the settings and addresses. - Your apps and coding agents: add an "OpenAI-compatible" provider with the base URL
http://127.0.0.1:8080/v1. Any API key and any model name work. - Thinking: choose off, low, medium or high in the chat menu or in your app's "reasoning effort". Off is the fastest. High is best for hard questions.
- From your phone or another PC:
START-HERE.bat --setup --host 0.0.0.0 --api-key <secret>. Always set a key.
Where they differ:
| Qwen3.8-Flash-Next | GLM 5.3 Flash | DeepSeek V4 Flash | LFM2.5-24B-A2B | Qwen3.6-35B-A3B, Ornith 1.5, Gemma 4 26B-A4B, Tiel Coder 35B-A3B, MiniCPM-V 4.7 35B-A3B | |
|---|---|---|---|---|---|
| Pictures | Say yes to "Images?" in setup. Then click Picture in the chat, or attach pictures in your app. AMD cards read pictures on Linux through the processor; on Windows they can't yet. | Not yet. | It reads text only. | It reads text only. | Say yes to "Images?" in setup, then as with Qwen3.8-Flash-Next. On a card with less than 16 GB the picture encoder runs on the processor, and a picture takes a few seconds. |
| Several requests | One at a time by default, the others wait. "parallel": 2 answers several at once (BATCHING.md); on a 12 GB card each answer gets slower. |
One at a time, the others wait. | One at a time, the others wait. | One at a time, the others wait. | One at a time, the others wait. |
| Several conversations | The last one is kept, so follow-up messages start in seconds. Two engine arguments keep several in RAM (details). | The last one is kept. Setup asks whether to keep several in RAM, so that an agent and its subagents take turns without their prompts being read again (how). | As GLM 5.3 Flash. | As GLM 5.3 Flash. | As GLM 5.3 Flash. |
| Long prompts | The first message of a chat is read in full, about 1 minute per 30,000 tokens. | The first message is read in full, about 40 seconds per 30,000 tokens. | The first message is read in full, about 29 seconds per 30,000 tokens. | The first message is read in full: 30,000 tokens take 1.3 to 1.5 seconds on the workstation and 8 to 10 seconds on the 8 GB laptop. | The first message is read in full: 30,000 tokens take 4 to 5 seconds on the workstation and 14 to 27 seconds on the 8 GB laptop. |
More: where your chats are stored, the API.
Optional: more speed on one card when the whole model fits in RAM
Two opt-in settings (by RubenTorney, #1904 and #1905). They help when you run one graphics card and your RAM holds
every expert (PolyStrata's arena mode, for example Q2_0 or IQ3_XXS on a 64 GB PC). Open your config,
strata-<model>.json in the PolyStrata data folder (where), and add:
- Faster decode:
"--adapt-async", "1"to the"args"list. The expert cache then updates on a helper thread instead of pausing the answer. Measured on an RTX 5070 (Windows, Q2_0): +4-5% decode, +7-10% on code and long documents. Answers can differ slightly from the default (they stay the same from run to run). - Faster prompt reading on Windows:
"STRATA_PIN_BY_NEED": "1"in the"env"block. Windows can lock only about half the RAM for the graphics card; this locks the experts the card actually needs first. Measured on the RTX 5070: +4.4% prompt reading.
"args": [ ..., "--adapt-async", "1" ],
"env": { "STRATA_PIN_BY_NEED": "1" }
Restart PolyStrata (START-HERE.bat or ./setup.sh) after the change. To undo, remove the two entries.
Something went wrong?
- My PC froze the first time PolyStrata started. This is normal while it loads the model. Wait, and don't close the window. Still frozen after 10 minutes? Restart the PC, close other programs and try again, or pick a smaller size.
- It stopped while downloading or installing. Run
START-HERE.bat(or./setup.sh) again. It continues where it stopped. - It's very slow and the disk light keeps blinking, or it says "the engine stopped unexpectedly". Your PC does not have enough free RAM. Close other programs (browsers use a lot), or pick a smaller size (Q2_0 or IQ2_XS).
- It says port 8080 is already in use. PolyStrata is already running. Look for its window.
More problems and their fixes: docs/TROUBLESHOOTING.md. Still stuck? Open an
issue and attach strata-<model>.log from the PolyStrata folder. Found a
security problem? Report it privately: SECURITY.md.
How does it work?
Models like these usually run on servers with hundreds of gigabytes of graphics memory. Your graphics card has 8-32 GB. PolyStrata makes the model fit by sharing the work across your whole PC. Think of a kitchen: the things you use all the time stay on the counter, and the rest waits in the pantry.
Qwen3.8-Flash-Next
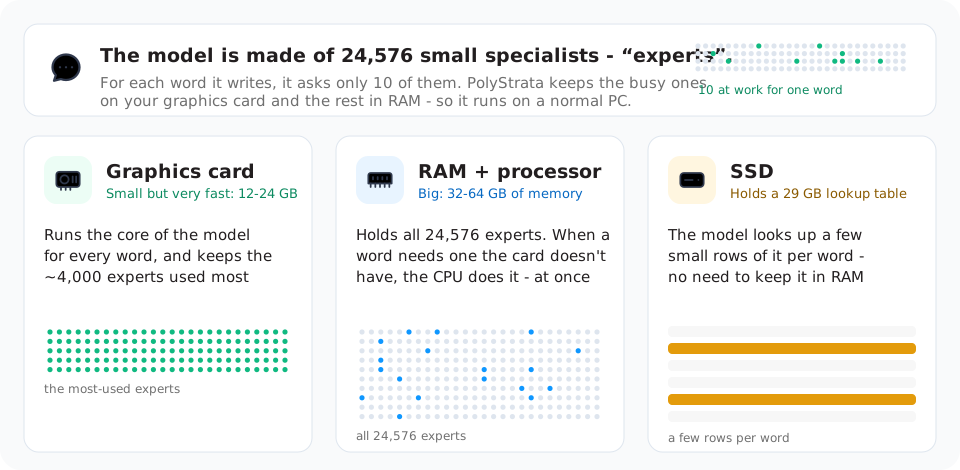
- The model is a team of 24,576 small specialists ("experts"). Each word needs only 10 of them.
- Your graphics card keeps the few thousand experts that are used most often. Your RAM holds all of them, and your processor works on the rest at the same time. Your SSD holds a big lookup table.
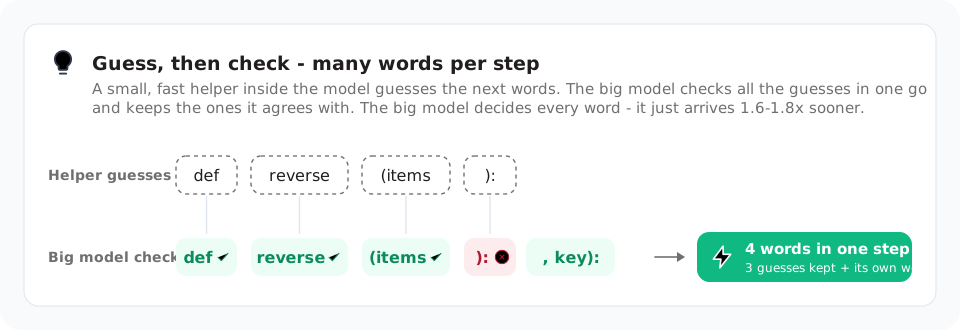
- Guess, then check: a small helper guesses the next few words. The big model checks them all at once. You get the same answer, 1.6-1.8x sooner.
- Long texts are read in big pieces (up to 8,192 tokens at a time), at over 1,000 tokens per second.
The longer explanation: docs/HOW_IT_WORKS.md. Every part and its numbers: the details and the paper.
GLM 5.3 Flash
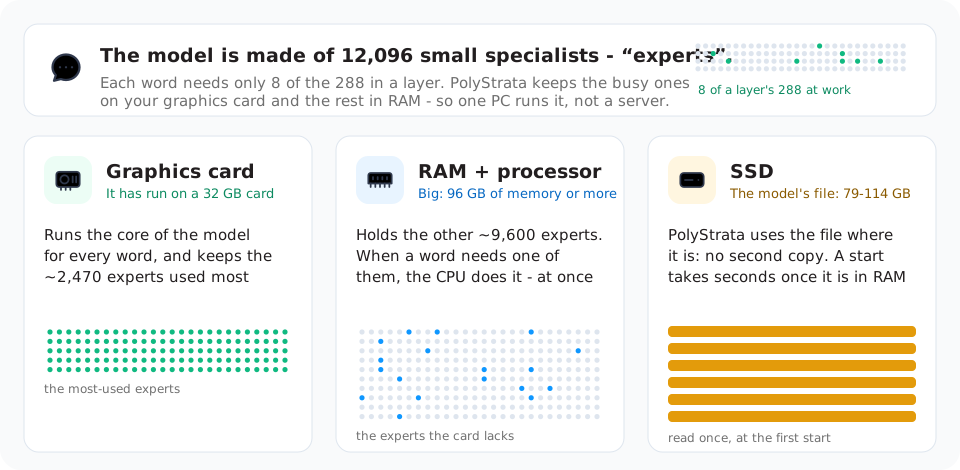
- The model is a team of 12,096 small experts, 288 in each of 42 layers. Each word needs only 8 from every layer.
- Your graphics card keeps the ones used most often, about 2,470 of them on a 32 GB card: the engine counts which ones your work uses and chooses again at the next start. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy; a start takes about 6 seconds once the file is in your RAM.
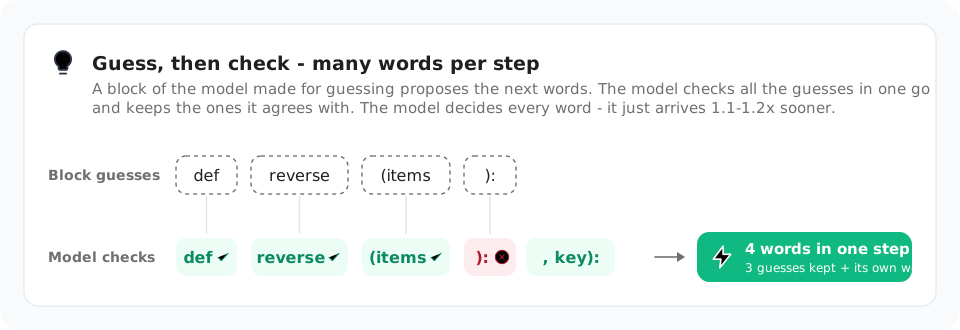
- Guess, then check: a block of the model made for guessing proposes the next few words. The model checks them all at once. You get the same answer, 1.1-1.2x sooner.
- Long texts are read in big pieces (1,024 tokens at a time, the experts the card does not hold passing through it), at 780 to 1,250 tokens per second.
Every part and its numbers: docs/GLM.md.
DeepSeek V4 Flash
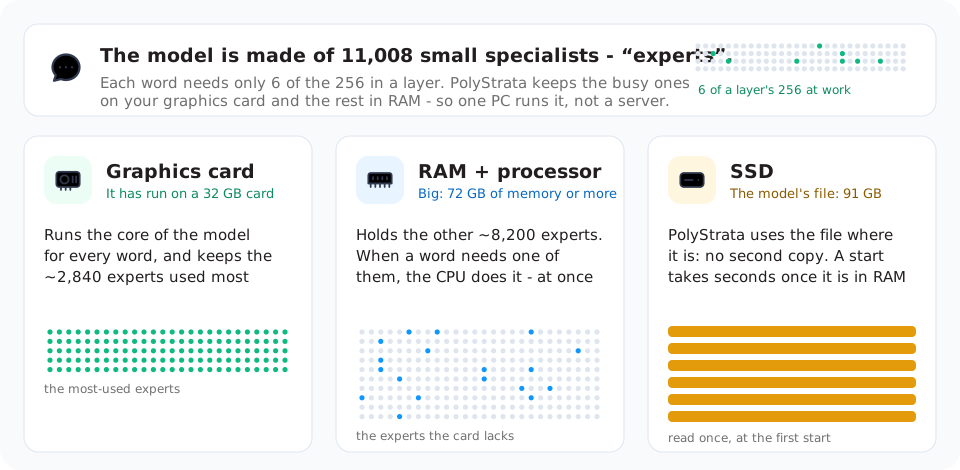
- The model is a team of 11,008 small experts, 256 in each of 43 layers. Each word needs only 6 from every layer, beside one that every word uses.
- Your graphics card keeps the ones used most often, about 2,840 of them on a 32 GB card: the engine counts which ones your work uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's files, which are used where they are, with no second copy.
- A small memory of the conversation: a word reads the last 128 words in full and the rest as compressed rows, one for every 4 or every 128 words. A token of context takes 6,880 bytes, so a long context leaves the card nearly all of its room for experts.
- Long texts are read in big pieces (1,024 tokens at a time), 30,000 tokens at about 1,000 tokens per second. It has no guess-then-check yet: the draft model made for it is not run.
Every part and its numbers: docs/DEEPSEEK.md.
LFM2.5-24B-A2B
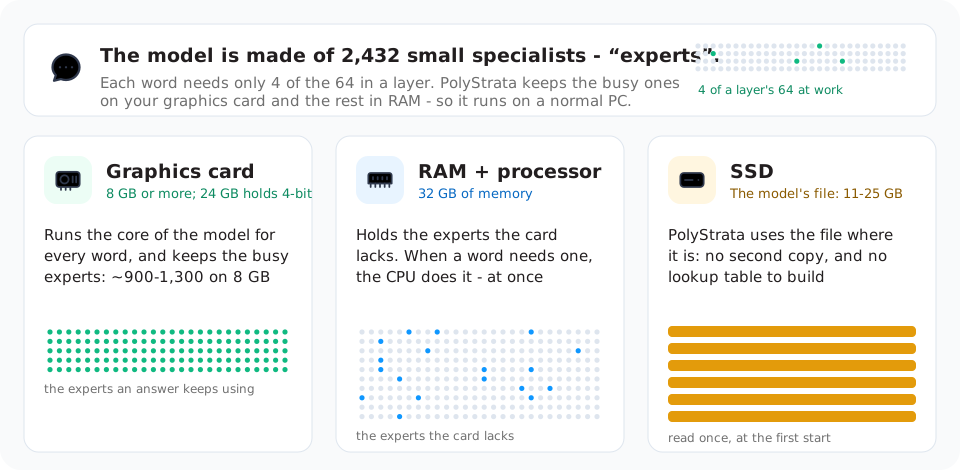
- The model is a team of 2,432 small experts, 64 in each of 38 layers. Each word needs only 4 from every layer.
- Most of its 40 layers have no attention. 30 of them mix the words with a short convolution over the last three, which keeps two vectors a layer. Only the other 10 keep the whole conversation, so its memory of a conversation is small: a 128K context takes 2 GB more VRAM than 32K.
- Your graphics card keeps as many experts as fit: about 900 to 1,300 of them on an 8 GB card, all of them from 24 GB on for the 4-bit sizes. On the 8 GB card the ones it holds serve two thirds to four fifths of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy.
- No draft block. The model has nothing that guesses ahead, so the engine guesses only from text the conversation repeats.
- When the card holds every expert, the whole step stays on the card: it routes the words to their experts and runs a token's 40 layers as one recorded launch.
Every part and its numbers: docs/LFM.md.
Qwen3.6-35B-A3B
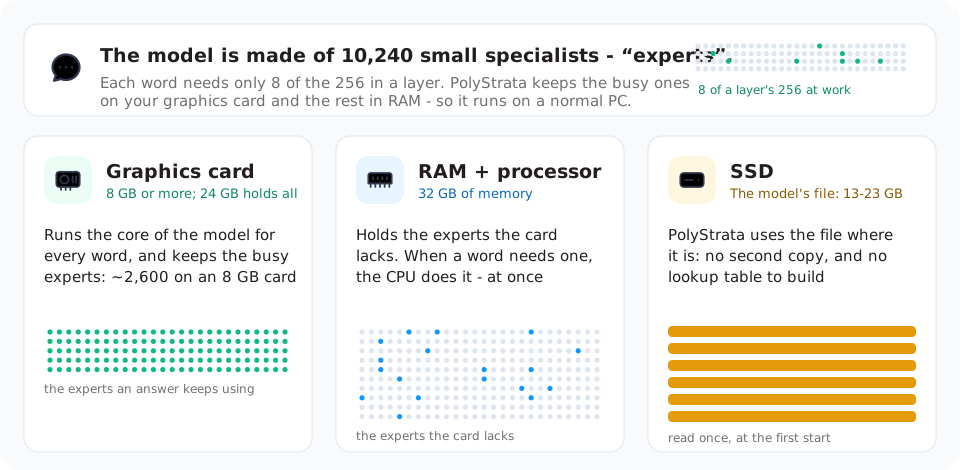
- The model is a team of 10,240 small experts, 256 in each of 40 layers. Each word needs only 8 from every layer.
- Your graphics card keeps as many as fit: about 2,600 of them on an 8 GB card, all of them from 24 GB on. While it writes, the engine brings in the experts the answer keeps choosing, and on the 8 GB card the ones it holds serve about 60% of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy.
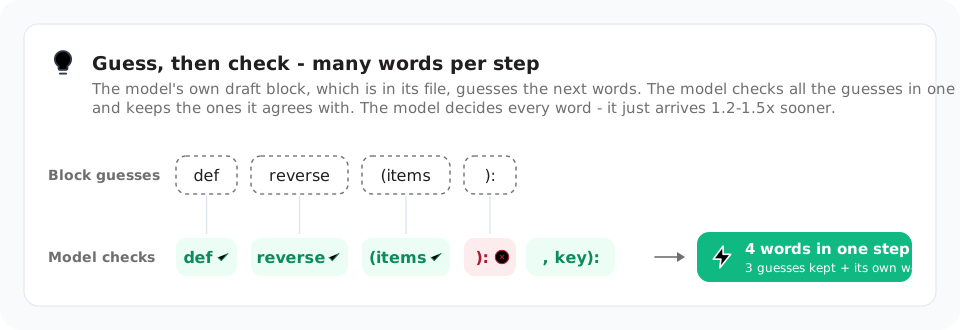
- Guess, then check: the model's own draft block, which is in its file, proposes the next few words. The model checks them all at once. You get the same answer, 1.2-1.5x sooner.
- Long texts are read in big pieces (1,024 tokens at a time). When the card does not hold every expert, the others pass through it once for the whole prompt.
Every part and its numbers: docs/BACKENDS.md.
Ornith 1.5
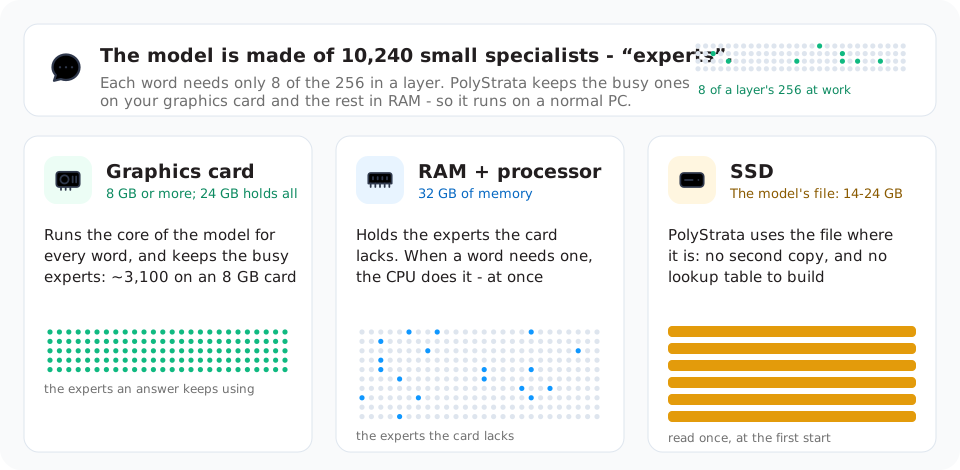
- Qwen3.6-35B-A3B's architecture with other weights: a team of 10,240 small experts, 256 in each of 40 layers, and only 8 of every layer for each word.
- Your graphics card keeps as many as fit: about 3,100 of them on an 8 GB card, all of them from 24 GB on. While it writes, the engine brings in the experts the answer keeps choosing, and on the 8 GB card the ones it holds serve about 60% of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy.
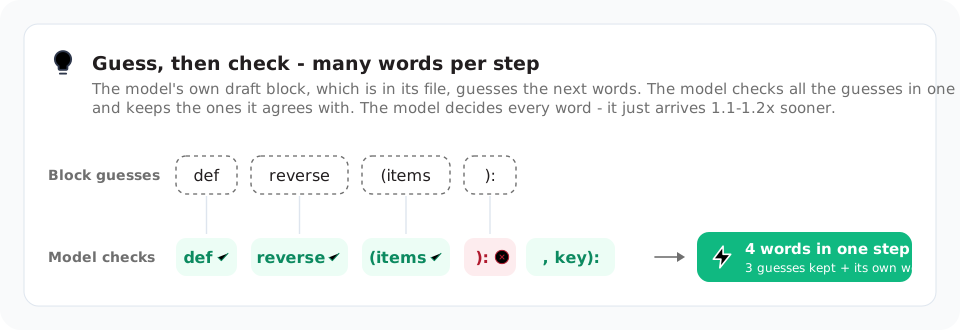
- Guess, then check: its draft block is in its file too, and proposes the next few words. It guesses right less often than Qwen3.6-35B-A3B's, so you get the same answer 1.1-1.2x sooner.
- Long texts are read in big pieces (1,024 tokens at a time). When the card does not hold every expert, the others pass through it once for the whole prompt.
Every part and its numbers: docs/BACKENDS.md.
Gemma 4 26B-A4B
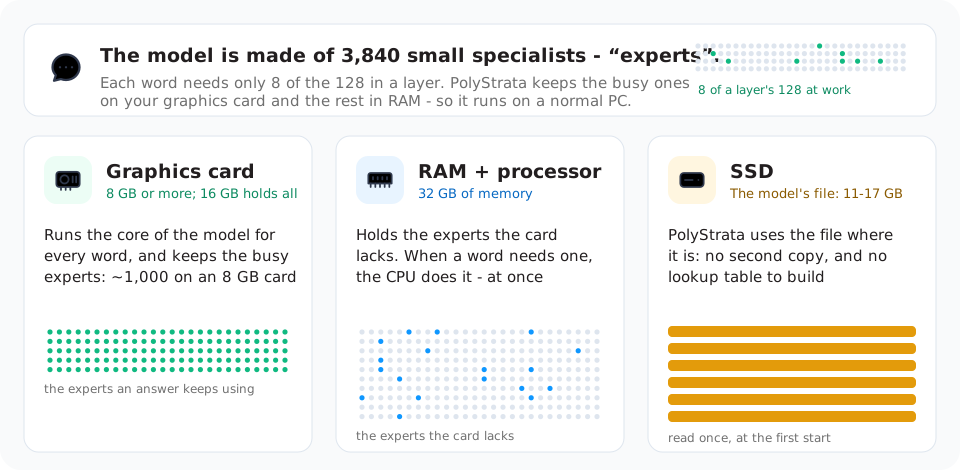
- The model is a team of 3,840 small experts, 128 in each of 30 layers. Each word needs only 8 from every layer, beside a part of the layer that every word uses.
- Your graphics card keeps as many as fit: about 1,000 of them on an 8 GB card, all of them from 16 GB on by the installer's estimate. While it writes, the engine brings in the experts the answer keeps choosing, and on the 8 GB card the ones it holds serve about 55% of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file and its draft model, which are used where they are, with no second copy.
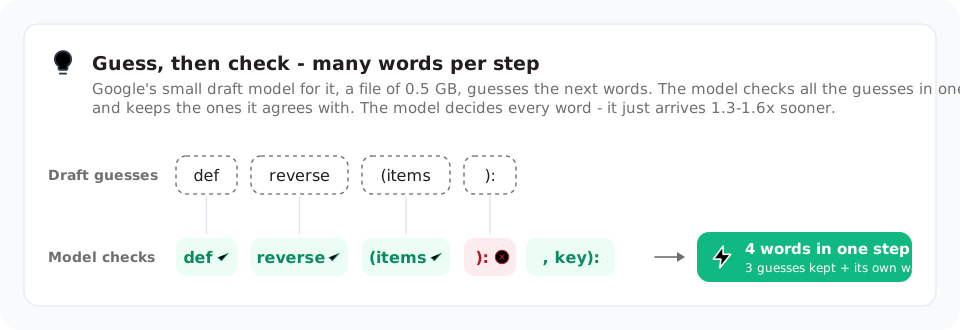
- Guess, then check: Google's small draft model for it, a file of 0.5 GB that the installer downloads with the model, proposes the next few words. The model checks them all at once. You get the same answer, 1.3-1.6x sooner.
- Long texts are read in big pieces (1,024 tokens at a time). When the card does not hold every expert, the others pass through it once for the whole prompt.
Every part and its numbers: docs/BACKENDS.md.
Tiel Coder 35B-A3B
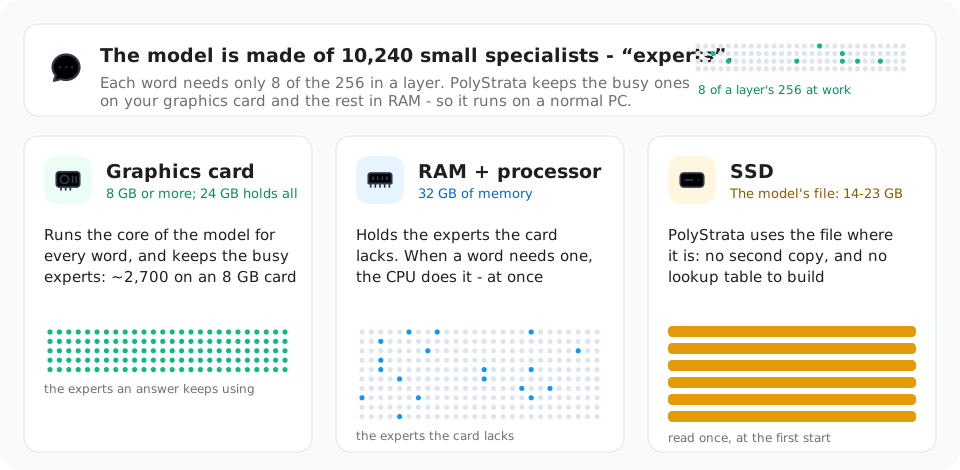
- Ornith 1.5 in another quantization: a team of 10,240 small experts, 256 in each of 40 layers, and only 8 of every layer for each word.
- Your graphics card keeps as many as fit: about 2,700 of them on an 8 GB card, all of them from 24 GB on. While it writes, the engine brings in the experts the answer keeps choosing, and on the 8 GB card the ones it holds serve about 50% of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy.
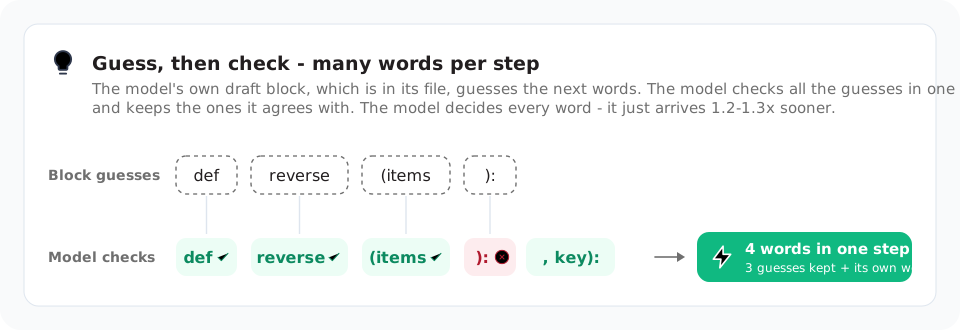
- Guess, then check: its draft block is in its file too, and proposes the next few words. It guesses right less often than Qwen3.6-35B-A3B's, so you get the same answer 1.2-1.3x sooner.
- Long texts are read in big pieces (1,024 tokens at a time). When the card does not hold every expert, the others pass through it once for the whole prompt.
Every part and its numbers: docs/BACKENDS.md.
MiniCPM-V 4.7 35B-A3B
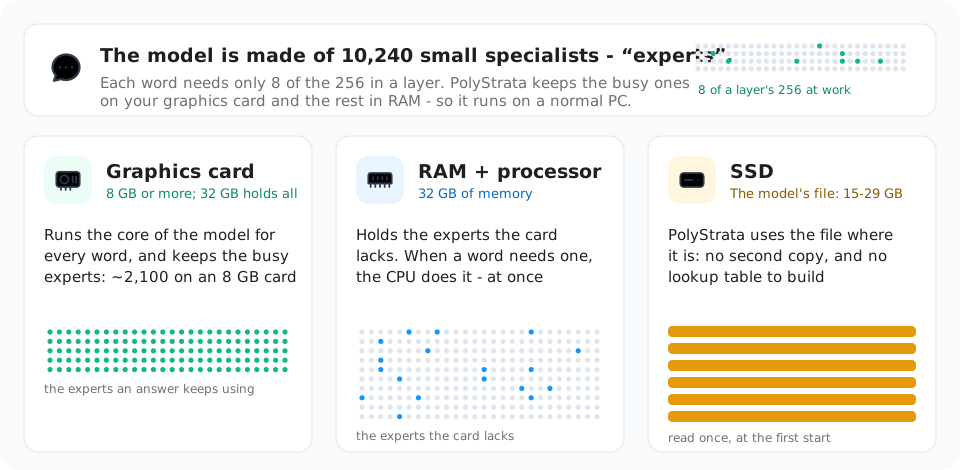
- Qwen3.6-35B-A3B's architecture with OpenBMB's weights: a team of 10,240 small experts, 256 in each of 40 layers, and only 8 of every layer for each word.
- Your graphics card keeps as many as fit: about 2,000 of them on an 8 GB card with Q4_K_M, all of them on a 32 GB card. While it writes, the engine brings in the experts the answer keeps choosing, and on the 8 GB card the ones it holds serve about 60 to 70% of what an answer uses. Your RAM holds the rest, and your processor runs them at the same time. Your SSD holds the model's file, which is used where it is, with no second copy.
- One word at a time: its file has no draft block, so nothing guesses ahead.
- Pictures: its own picture encoder reads a large picture as an overview and a few tiles. A screenshot of 1,200 by 398 pixels becomes about 300 tokens, a chart of 2,520 by 1,620 about 600.
- Long texts are read in big pieces (1,024 tokens at a time). When the card does not hold every expert, the others pass through it once for the whole prompt.
Every part and its numbers: docs/BACKENDS.md.
Credits and license
Qwen3.8-Flash-Next is by the Qwen team. It was compressed by ISTA-DASLab, UkisAI (Swift 1.5) and Unsloth. GLM 5.3 Flash runs from the files of neuralll, Unsloth and patrickbdevaney. Qwen3.6-35B-A3B is by the Qwen team, Gemma 4 by Google and DeepSeek V4 Flash by DeepSeek, all three in Unsloth's quantization. LFM2.5-24B-A2B is by Liquid AI, in Unsloth's quantization and in Liquid AI's own QAD-Q4_0. Ornith 1.5 is by ornith-ai, in mudler's APEX quantization. Tiel Coder 35B-A3B is Ornith 1.5 in peculiar-ragdoll's quantization; u/Sensitive_Song4219 found that it runs on PolyStrata. MiniCPM-V 4.7 35B-A3B is by OpenBMB, in their own quantization; iMilnb brought it to PolyStrata. PolyStrata is built on Strata by Niko1221 and its contributors, and uses parts of llama.cpp / ggml. All credits: docs/HOW_IT_WORKS.md. PolyStrata is open source under the MIT License. A few parts and every model have their own licenses (which ones).